Grok 4.7 Is Here — And the Internet Immediately Broke SpaceX With It
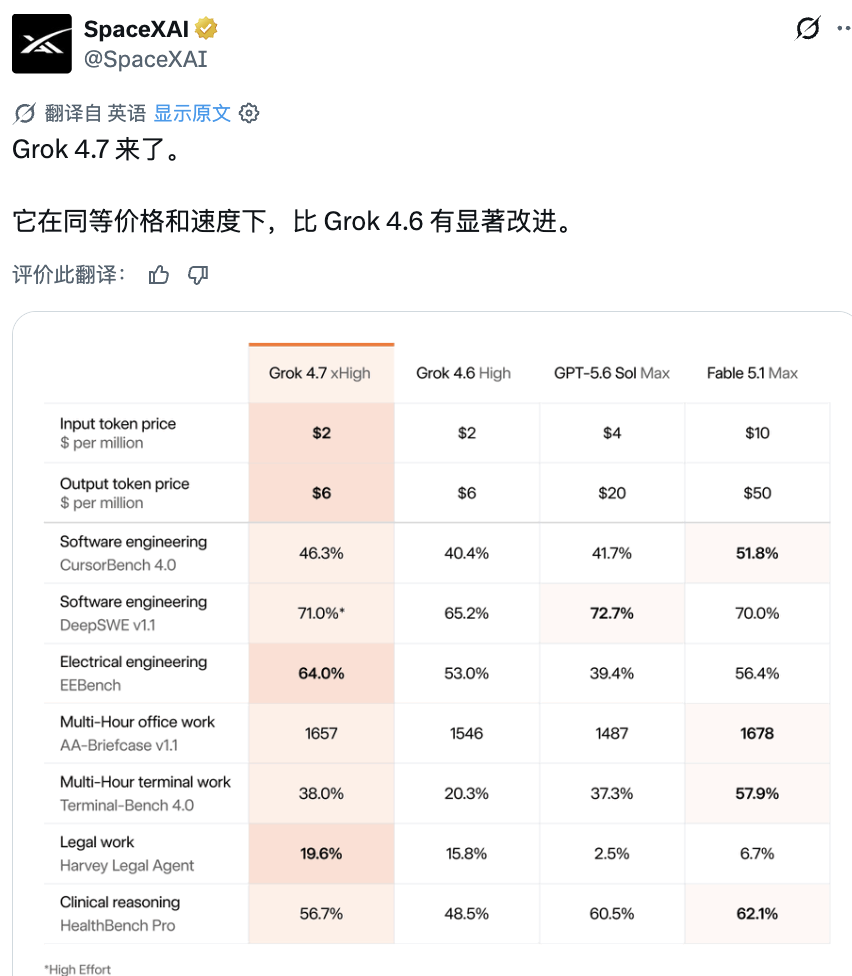
xAI shipped Grok 4.7 just ahead of the holiday rush: bigger base model, 500K context, heavy training on coding, agents and long-horizon tasks. EEBench takes first at 64%, terminal ops jump 20.3%→38%, Coding Agent Index hits 56 — at $2/$6 per million tokens, more model for the same price. The internet, naturally, used it to launch rockets and build the Golden Gate Bridge.
Grok 4.7 Is Here — And the Internet Immediately Broke SpaceX With It
Looks like Elon knew perfectly well that the foundation-model scene around the National Day holiday was going to be a bloodbath.
So he decided to fire first and claim the slot — Grok 4.7 is here!
A bigger base model, context stretched to 500K tokens, with heavy training focused on coding, agents, and complex tasks that can run for hours.
Software engineering, electrical engineering, long-horizon office work, terminal ops, and legal tasks all lit up at once.
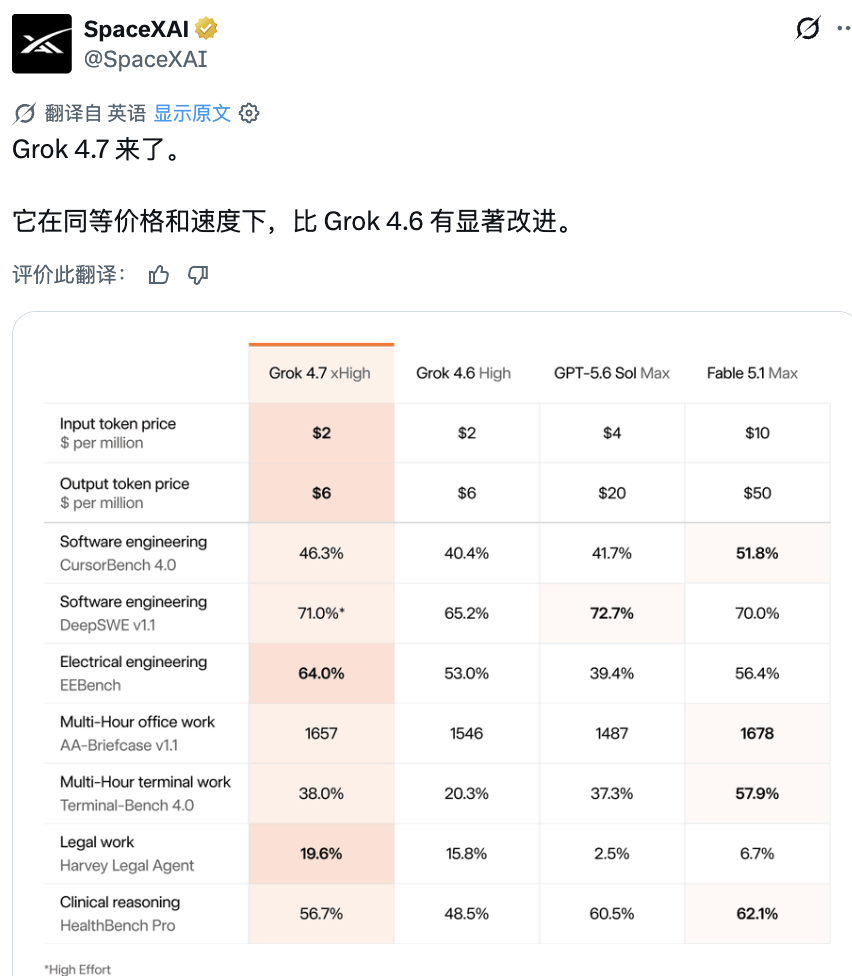
In the official eval table, the electrical engineering benchmark took first place at 64%, and terminal operation jumped from 20.3% to 38%.
And the pricing is delightful too: $2 per million input tokens, $6 per million output tokens. More model, same price.
But who'd have guessed — the moment the model dropped, the community's testing vibe went off the rails.
Coding? Agents? Legal reasoning? Put all that aside for a second.
As if everyone agreed on a signal in the group chat beforehand, the very first thing people did with Grok 4.7 was — LAUNCH ROCKETS!
@TheHype. staged a full "into the cosmos" production, and honestly, this rocket climbs even faster than the neighbor's:
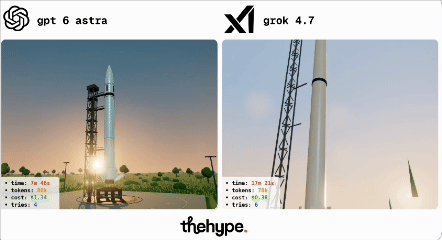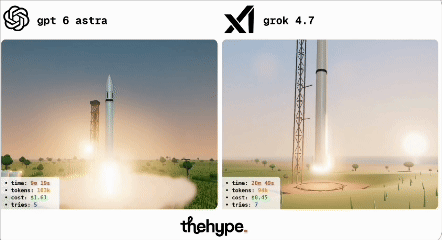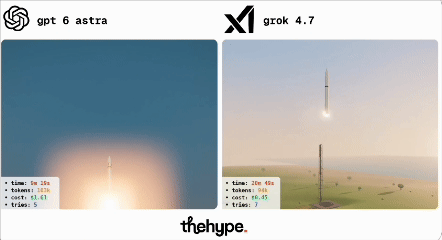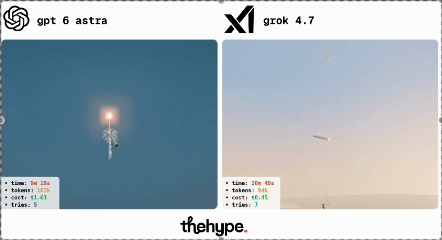
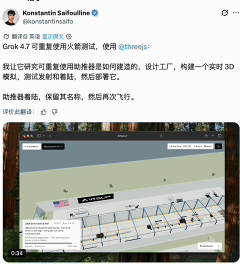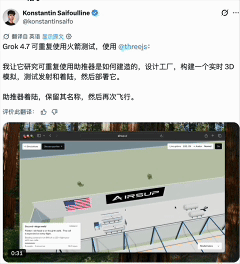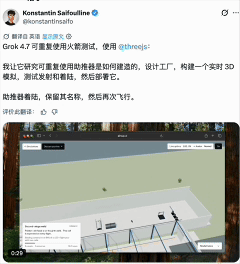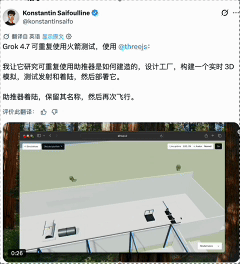
Then this guy had Grok 4.7 whip up a full 3D rocket engineering project — the vehicle, the launch pad, the works — and you can even test-fly it on the spot??
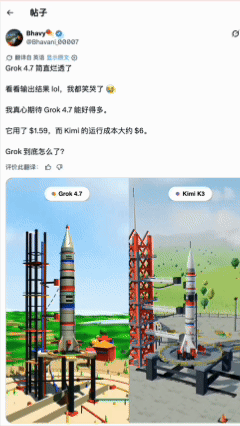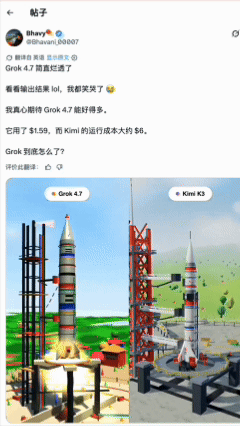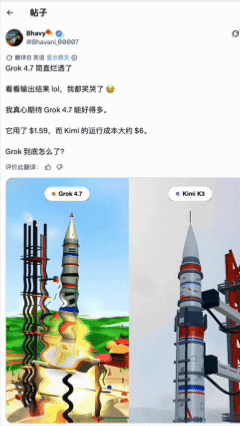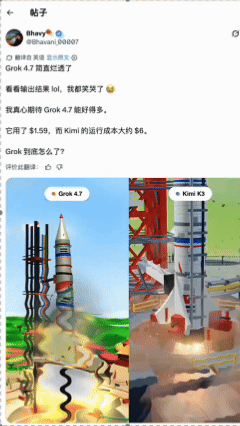
Another netizen, never one to miss a spectacle, dragged Kimi K3 and Grok 4.7 onto the same launch pad for an open-book shootout.
This round didn't go Grok's way — it more or less blacked out and slumped over, and the internet was not having it:
Elon: so this is how we're playing, huh??
SpaceX: what did I do wrong this time??
Grok 4.7 Is Training Specifically on Heavy, Complex Work
To sum it up in one line.
This release of Grok 4.7 is squarely aimed at "doing the heavy lifting."
Judging by the public eval results so far, Grok 4.7's gains are fairly concentrated — mainly coding, agents, and long-horizon tasks.
Start with xAI's own eval numbers.
Software engineering: CursorBench 4.0 rose from 40.4% to 46.3%, and DeepSWE v1.1 went from 65.2% to 71%.
Electrical engineering EEBench climbed even harder — up 11 percentage points over the previous generation, taking the highest score among the four models in the table. The gain on specialized engineering tasks is quite visible.
Legal agents also moved from 15.8% to 19.6%, opening up a gap in one go against GPT-5.6 Sol and Fable 5.1 in the same table:
Now to the third-party Artificial Analysis leaderboard.
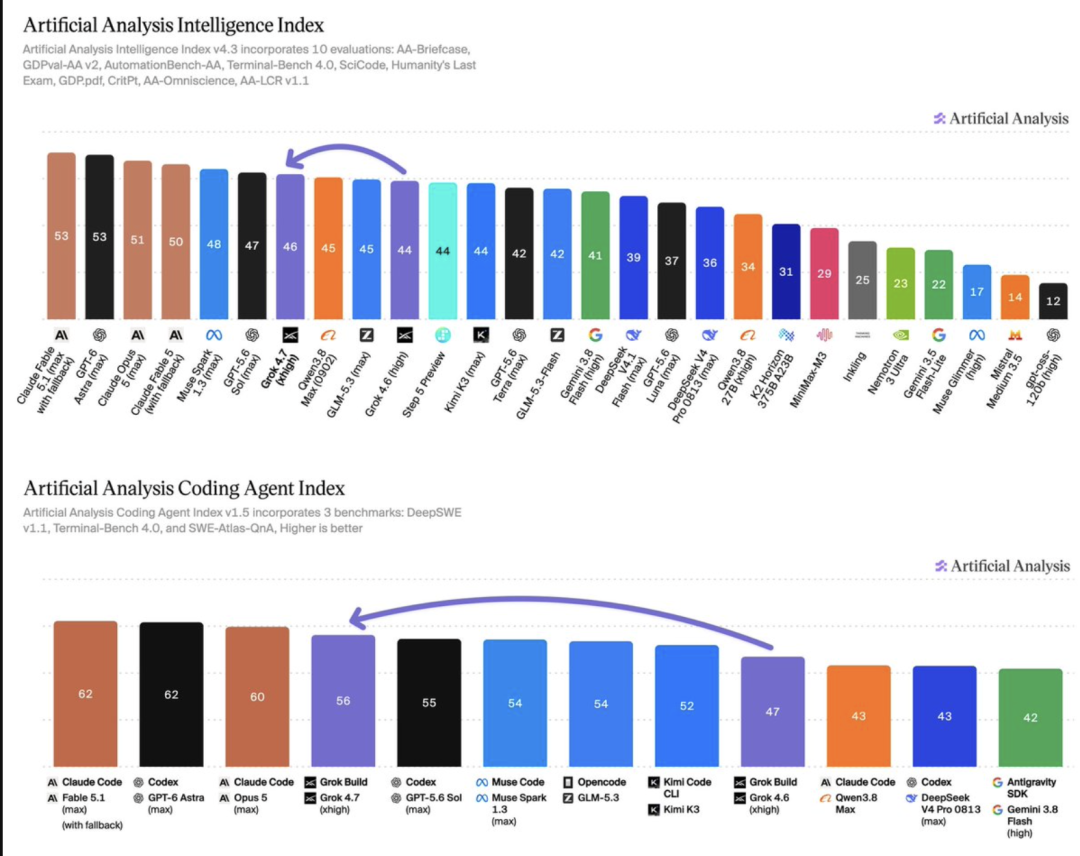
Its composite intelligence index hits 46, sitting just behind the first tier. On the more relevant Coding Agent Index, it lands at 56 — 4th place — a solid jump from Grok 4.6's 47.
Grok 4.7: can't beat the neighbor? Fine — I'll beat myself.
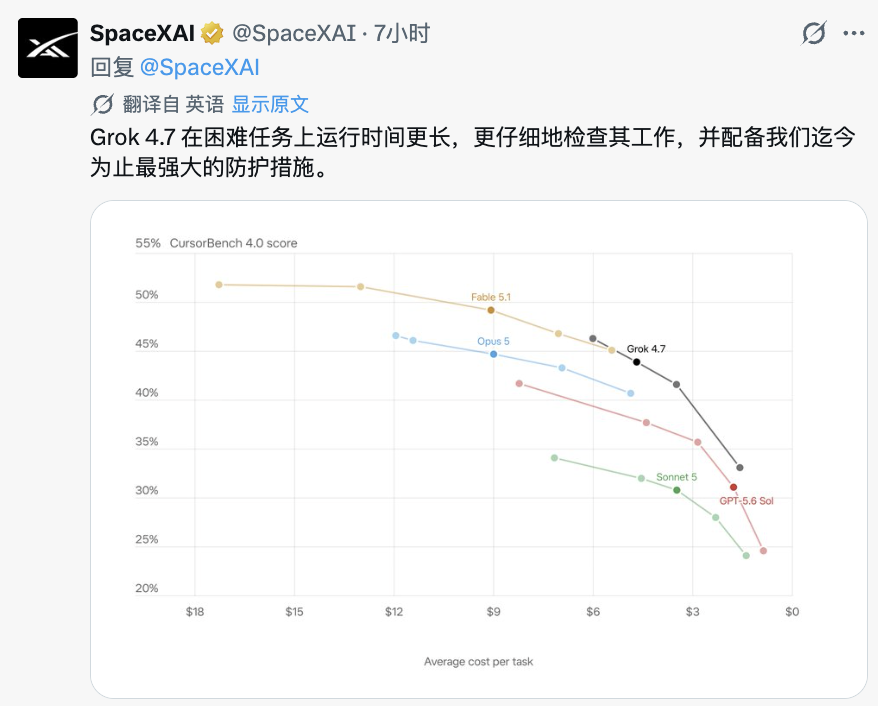
And Grok 4.7 isn't just scoring higher — its performance-cost ratio improved too.
In xAI's CursorBench 4.0 cost curve, Grok 4.7 keeps climbing as the per-task budget grows.
At around $4–5 per task it's already hitting roughly 43%, and more budget pushes it close to 46%.
For comparison, GPT-5.6 Sol sits at about 37% at the same budget — a gap of around 6 percentage points.
Hmm… which suggests that on complex coding tasks, spending a bit more inference budget on this generation does buy you more reliable capability gains?
After the Rockets, the Internet Dragged Grok 4.7 Into Game Dev and Bridge Building
More entertaining than the release itself: what people did with it.
Right after the rocket tests, everyone hauled Grok 4.7 into scenario after scenario to push it hard.
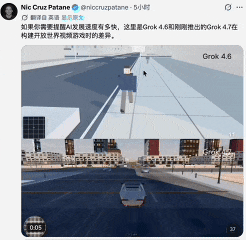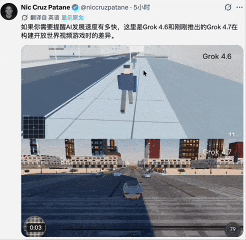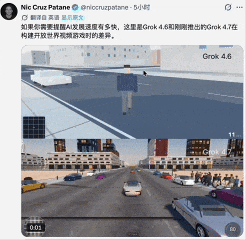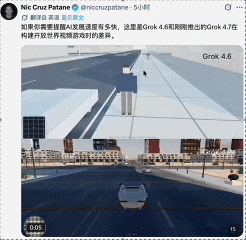
Below is a side-by-side of the open game worlds from Grok 4.6 and Grok 4.7 — the visual gap is pretty obvious.
4.6 still feels a bit like a pixel mini-game: flat imagery, fairly plain modeling (personal take).
With 4.7 the modeling is noticeably stronger — buildings, roads, lighting and scene detail are all more solid, and it genuinely starts to look like a proper 3D game demo:
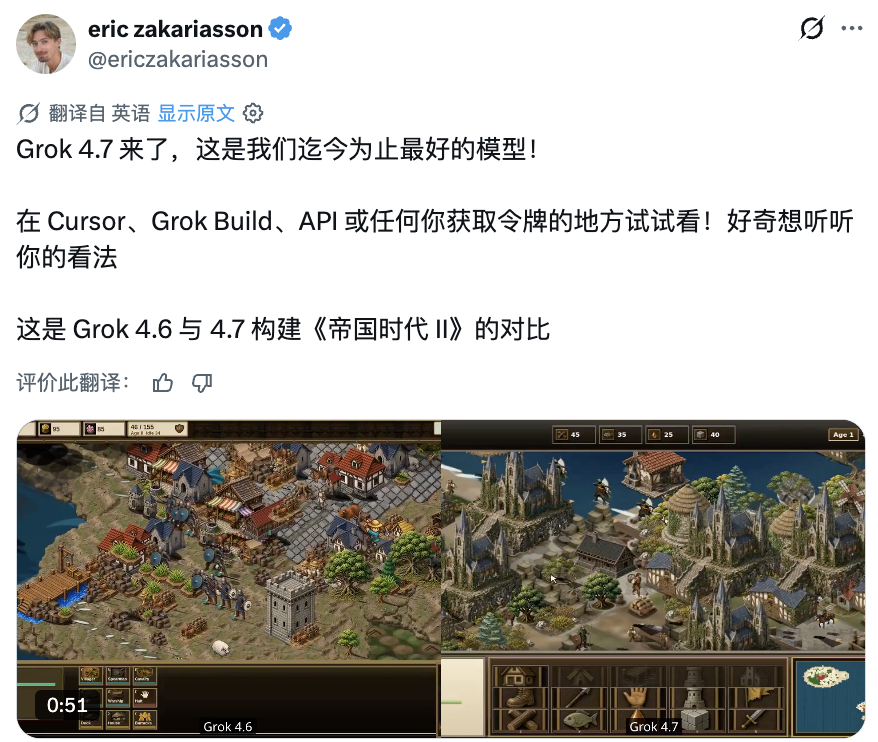
Next, this fellow had Grok 4.7 crank out an Age of Empires II.
On detail, it's clearly better than the previous generation's buildings — though 4.6's color palette arguably looked nicer. Different strokes, I guess. What do you think?
Then the difficulty ramped up again.
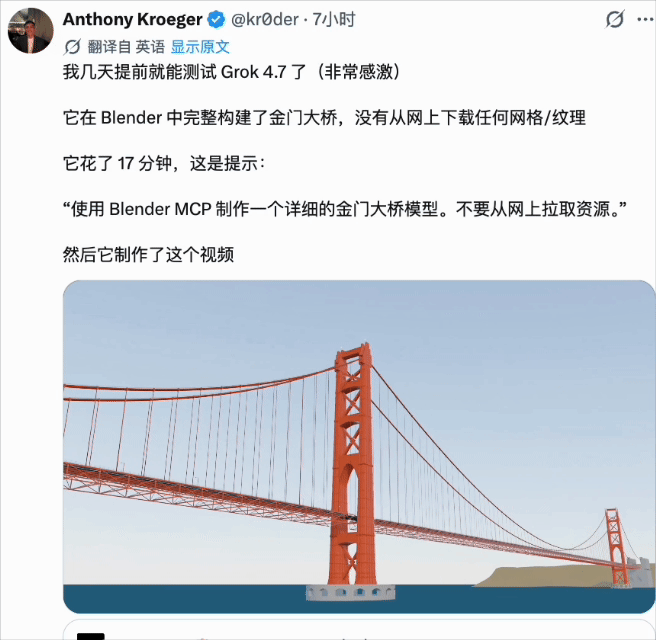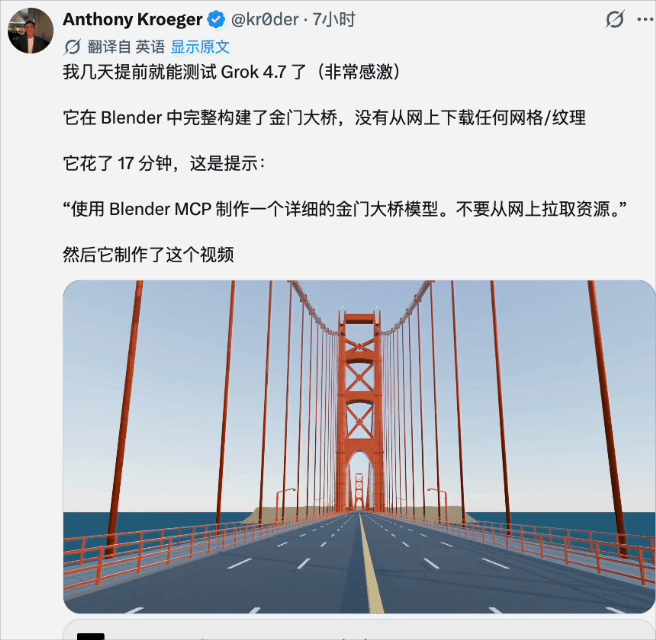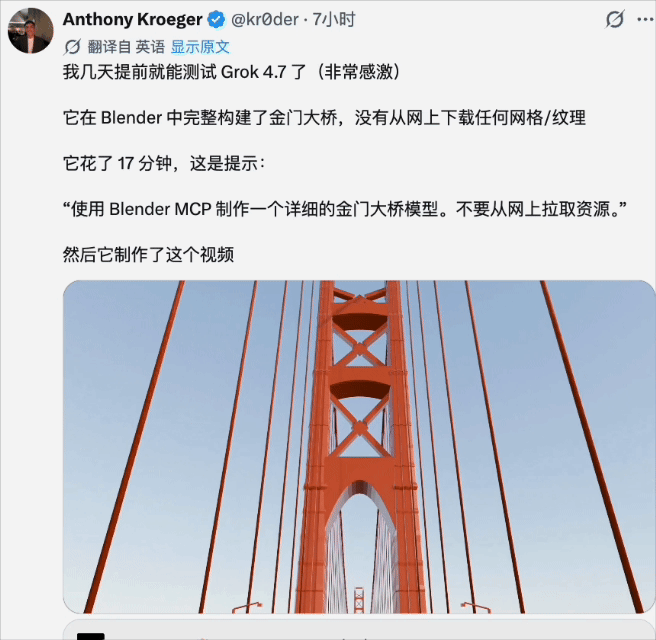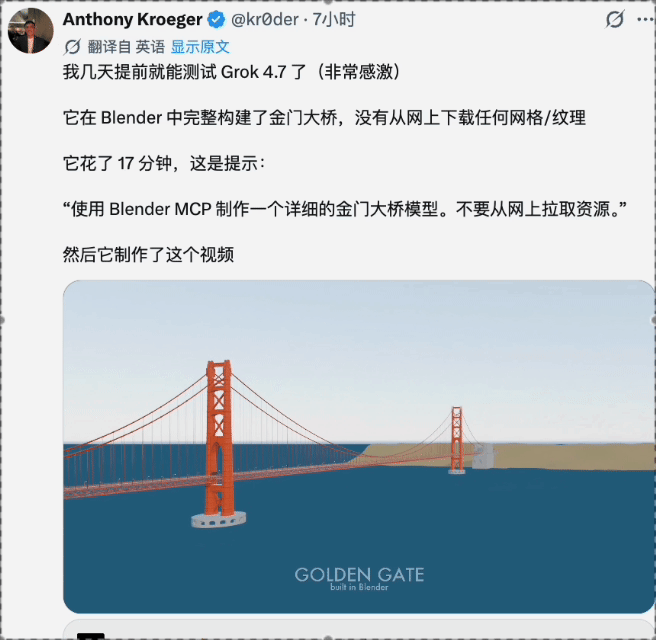
Someone dropped Grok 4.7 straight into Blender and had it build the Golden Gate Bridge on the spot.
The whole thing took just 17 minutes, with close-ups, wide shots and detail shots all present; the bridge structure and overall finish look pretty legit.
Judging by how proudly he posted the screenshots — those 17 minutes were money well spent!!!
And then there's this friend right here.
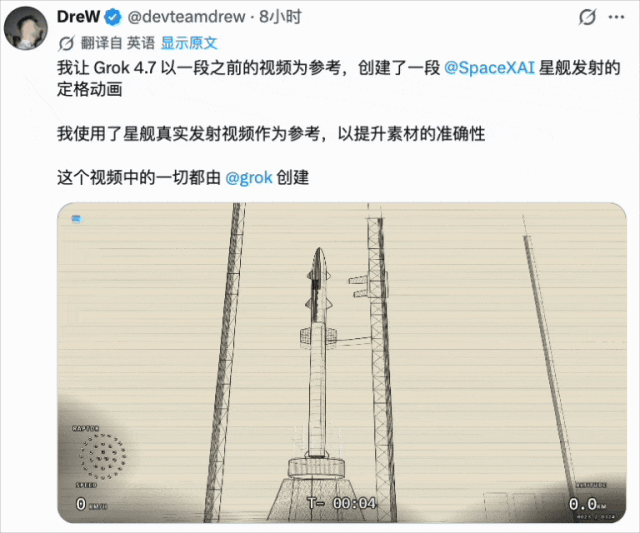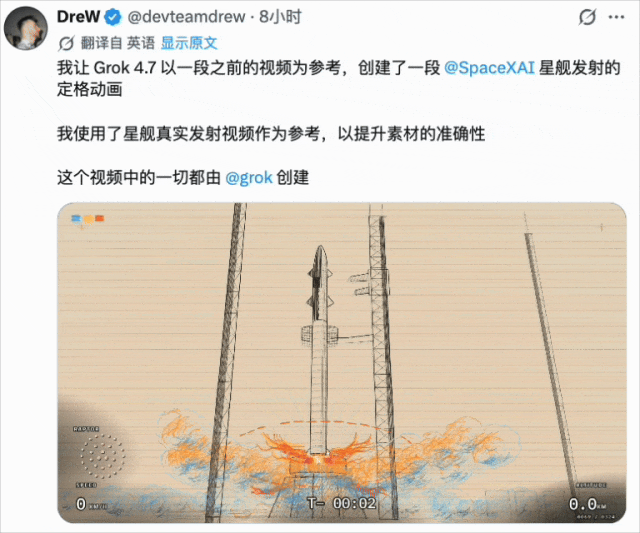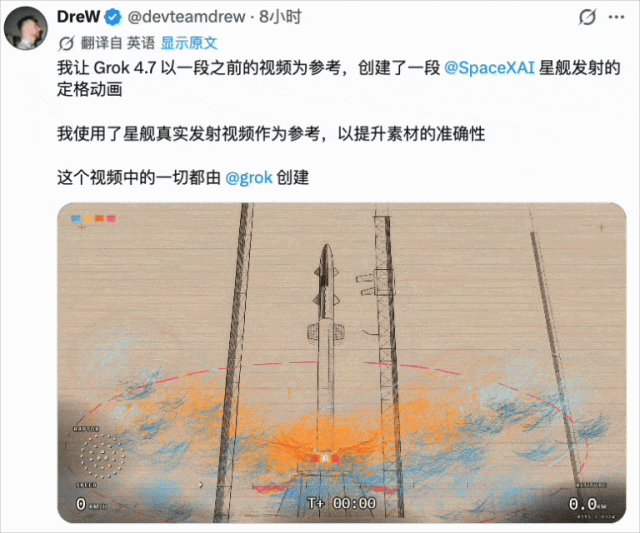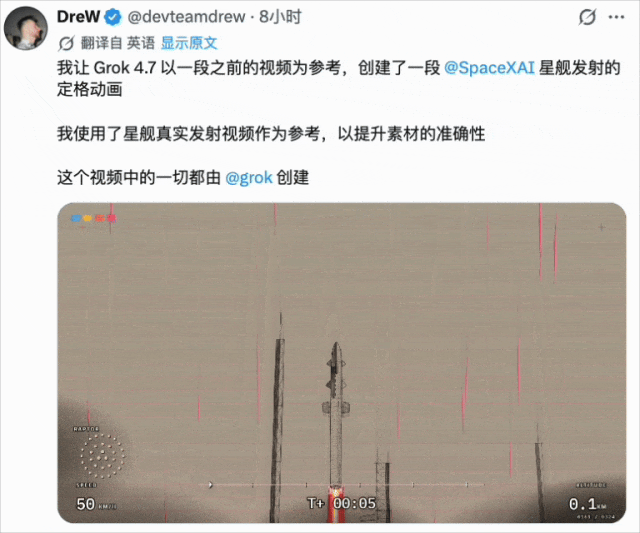
He fed Grok 4.7 a real SpaceX Starship launch video as reference and asked it to regenerate a stop-motion animation based on the real footage.
The final video came out in the style of a hand-drawn engineering sketch / retro stop-motion:
On the small-game front, someone came to spoil the party fast.
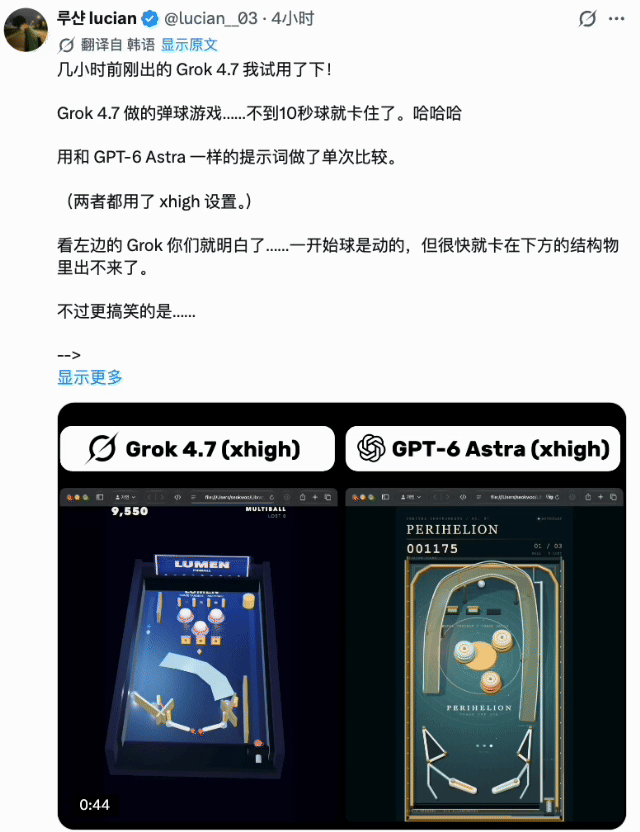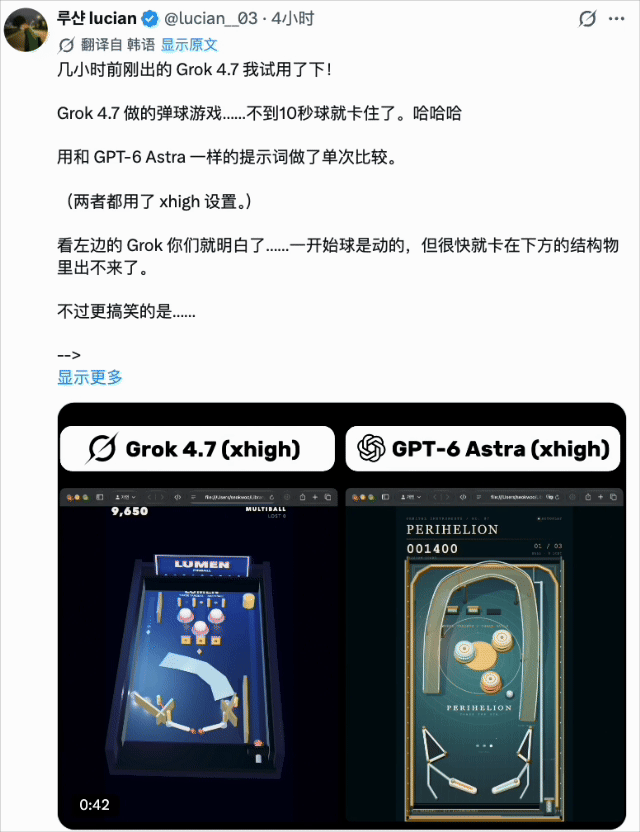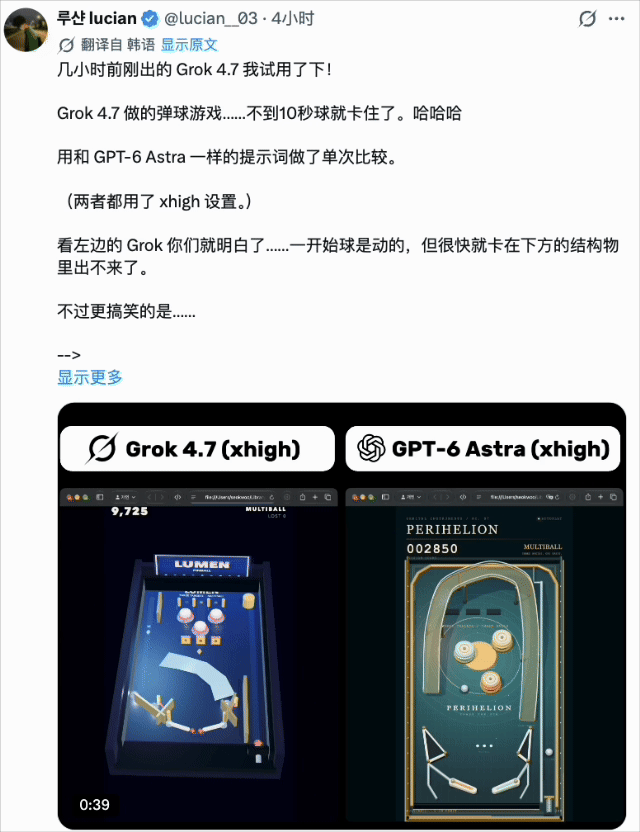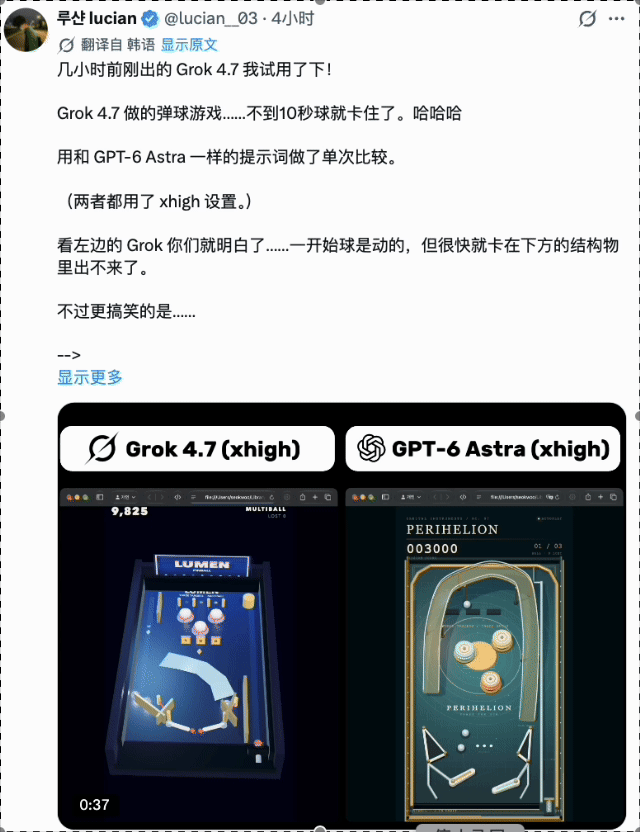
A netizen had Grok 4.7 and GPT-6 Astra each write a pinball game, and then things got awkward —
Grok's version started fine, the ball bounced, the visuals ran, and then in under 10 seconds the ball just froze.
Big jobs? No problem. Tiny balls? Can't handle them!!!
All told, there are only a few days left until the global foundation-model showdown on National Day.
Call it what you want — this is peak off-peak release timing.
Anthropic's Claude 5.2 is locked and loaded next door.
Google's Gemini 4 Pro internal tests are all over the timeline, and it's even suspected of sneaking into the Arena under an alias for a stealth exam.
Domestic players are piling onto the table too. These days around the holiday look very much like another round of foundation models handing in their papers together.
Shipping Grok 4.7 right now? Masterful move, honestly.
References:
[1]https://x.com/SpaceXAI/status/2102069815225586149?s=20
[2]https://x.com/SpaceXAI/status/2102069817893150777?s=20
[3]https://x.com/ArtificialAnlys/status/2102074898327932987?s=20
Channels Available in China
| Channel | Who it's for | Link |
|---|---|---|
| Grok mirror | Anyone who wants to try mainstream models straight in the browser | trygpt.asia |
| API aggregator | Developers — one key for many models | tryallapi.com |